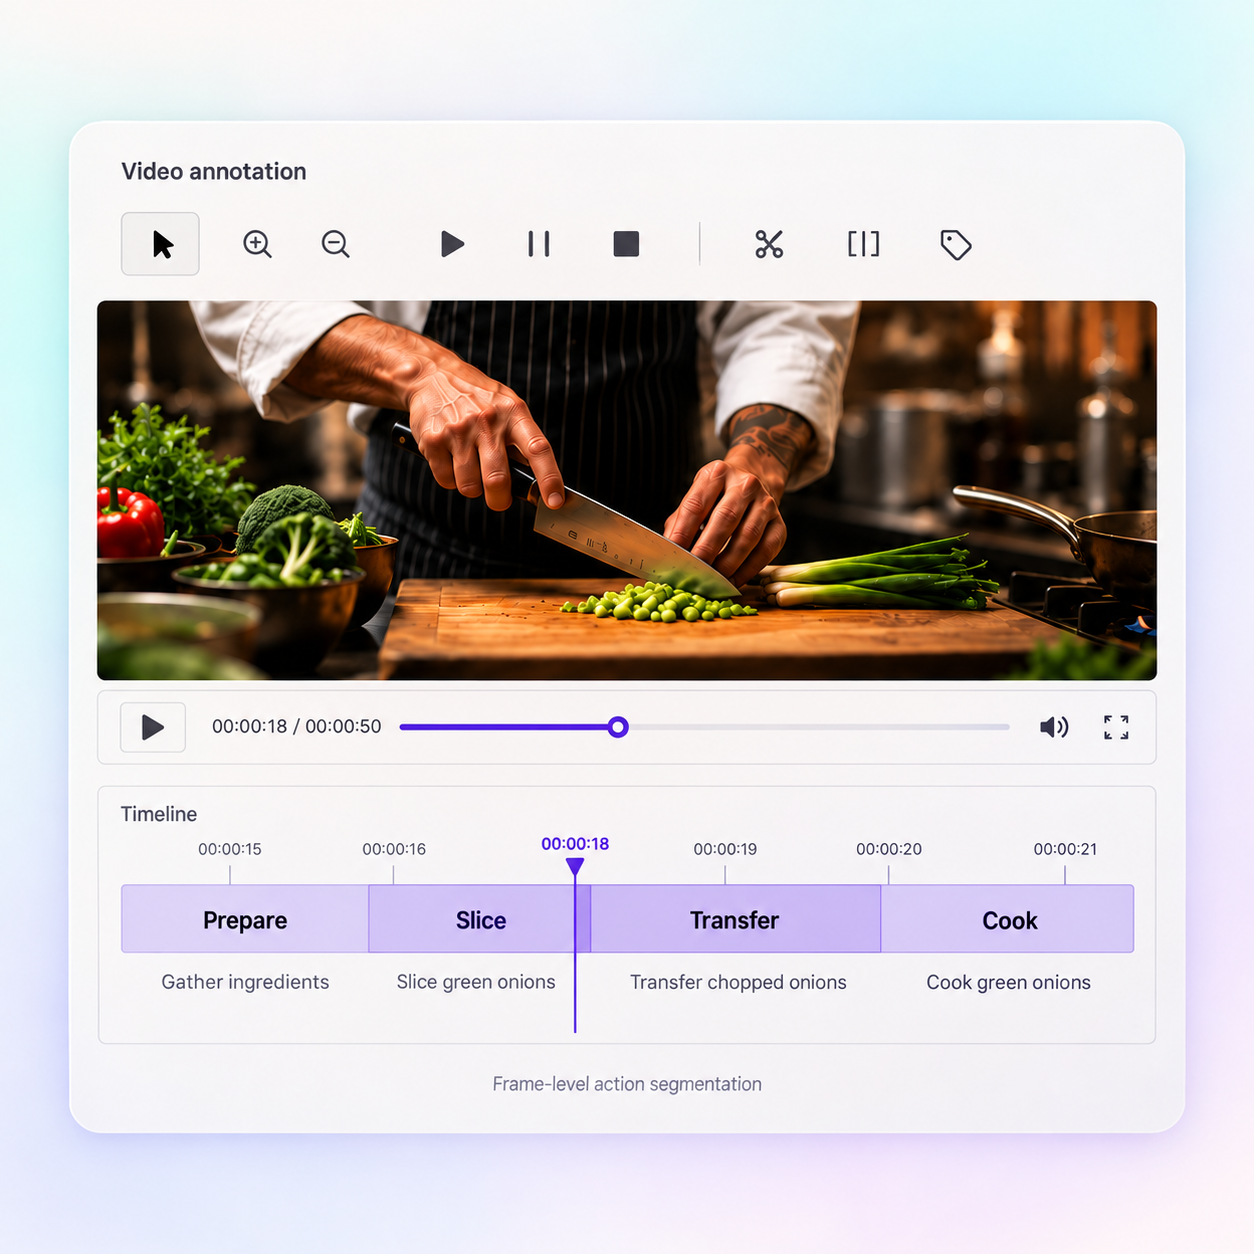
The client needed continuous footage divided into precisely defined actions, with consistent annotations across videos.

SUPA aligned reviewers through a pilot, documented ambiguous transitions and refined segmentation rules through feedback.

Delivered the first batch within 48 hours and established a repeatable annotation workflow.
The Problem
A generative AI company needed structured video data for model development. A typical 50-second clip contained around 45 action segments.
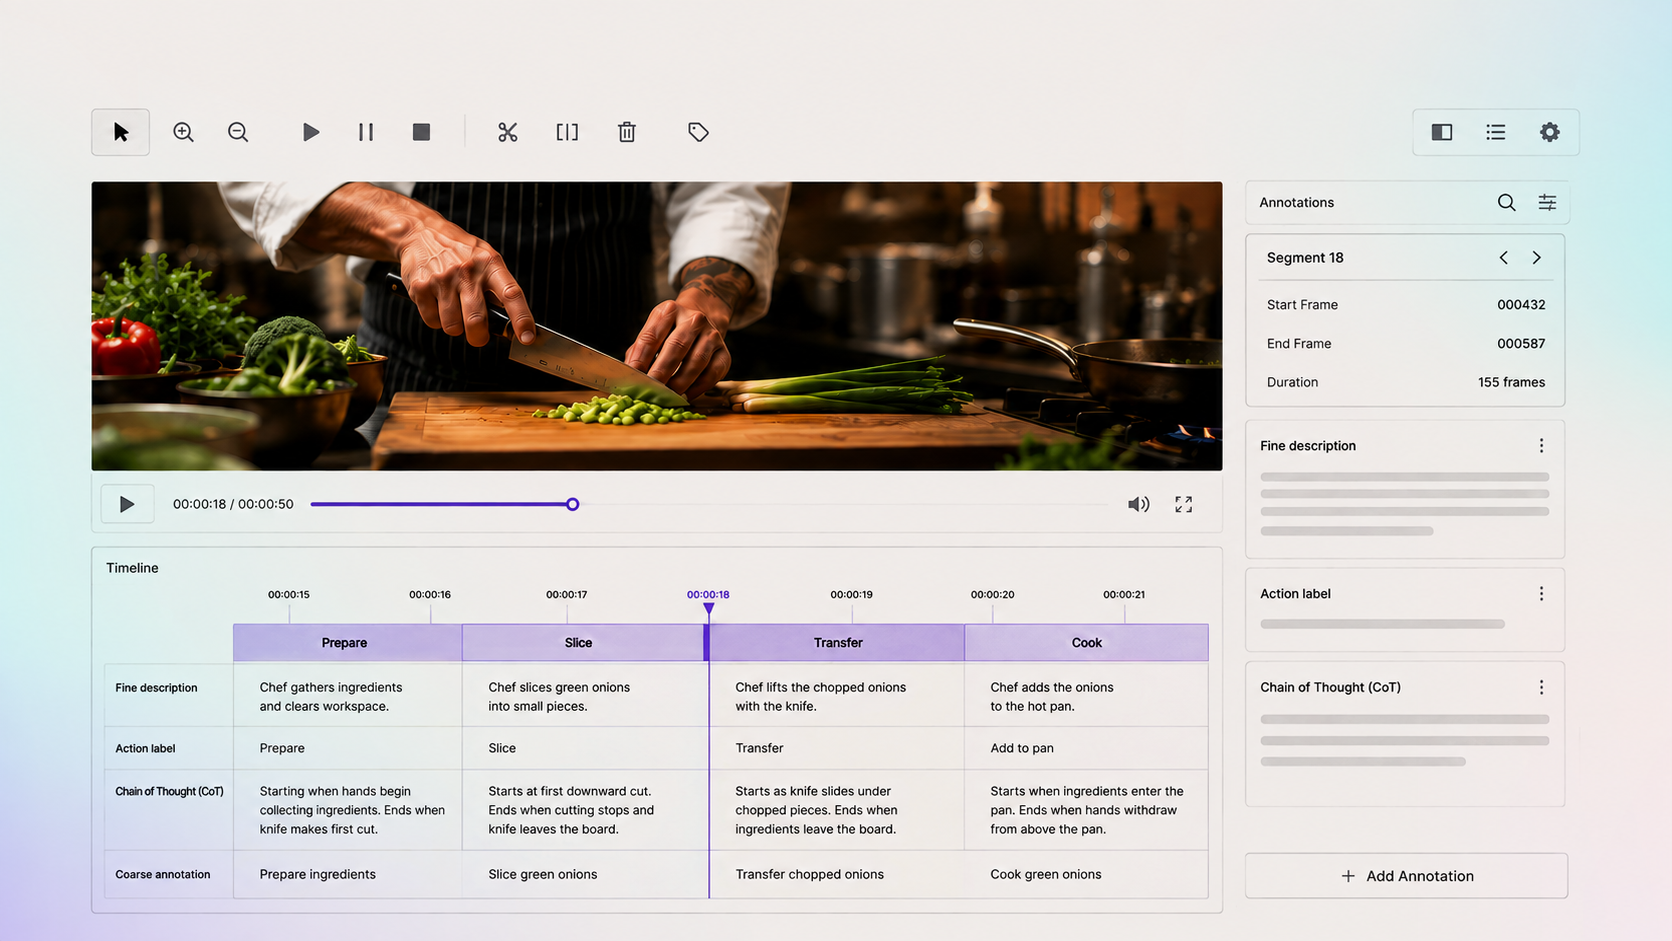
The challenge was deciding exactly where each action began and ended, keeping timelines continuous and applying the same interpretation across similar scenarios.
The Solution
SUPA started with a pilot to align annotation decisions before increasing throughput.
Each segment combined three aligned layers:
A broader summary captured the complete action. Reviewers documented edge cases and incorporated feedback into subsequent batches.
The Result
The first batch was delivered within 48 hours. The project established a repeatable workflow, with shared annotation standards supporting consistency across future batches.
Why SUPA?
Movement is continuous. Training data needs clear definitions.
For teams building systems that interpret physical activity, the value of an annotation lies in the judgment behind it: what counts as an action, which details deserve attention and how an unfamiliar example should be treated.
SUPA brings human expertise to those decisions. We work with your team to turn a technical brief into clear annotation guidance, helping bridge the gap between what a model needs to learn and what reviewers see.
Building models that need to understand movement? Let’s talk about your data.

SUPA leveraged domain-specific talent to source and label 600k stylized vector images, solving data diversity challenges

SUPA used a 12,000+ medical expert network to recruit 50 registered practitioners skilled in medical imaging interpretation.